What to inspect
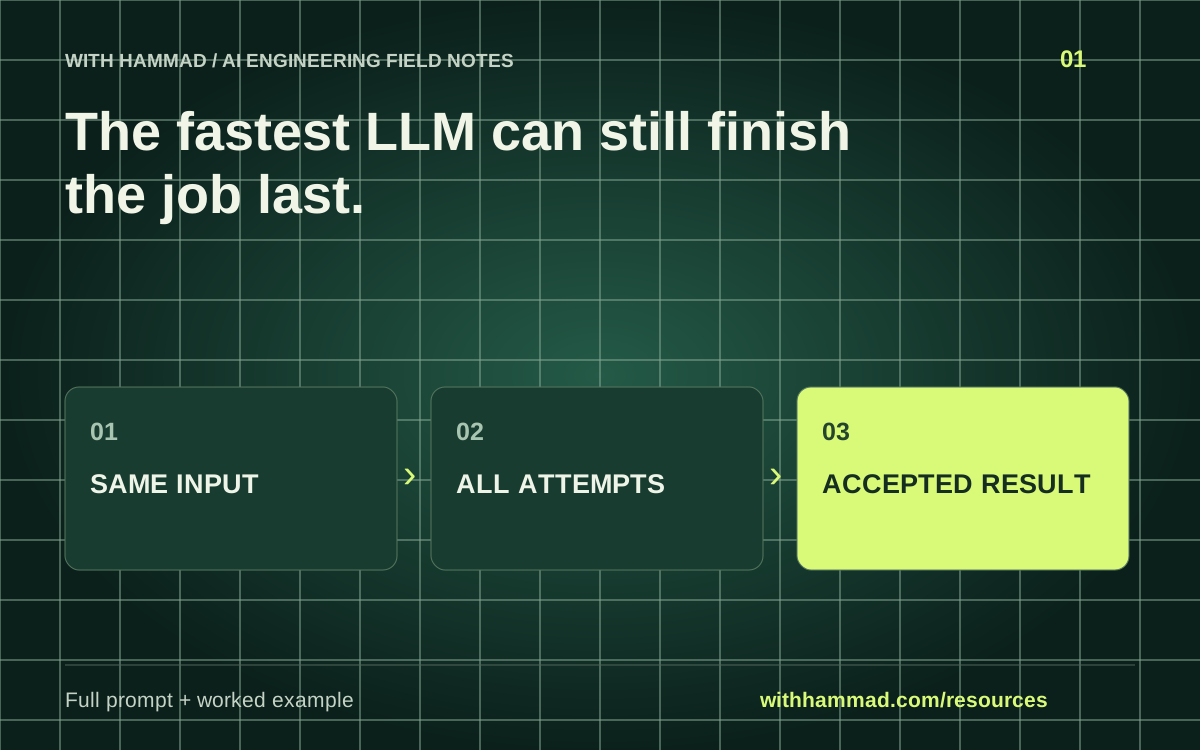
Choose one task and define acceptance before comparing models. Measure the complete workflow, including tool calls, rejected outputs and retries. Keep the input cases and tool access the same, and repeat trials to expose variation.
Worked example
Illustrative arithmetic: workflow A costs $0.02 per attempt and needs three attempts for one accepted result. Workflow B costs $0.04 and succeeds once. The accepted results cost $0.06 and $0.04 respectively. These are invented inputs to explain the calculation, not measured model prices.
Copy the full prompt
Adapt the inputs to your task. Remove private data before sending anything to a model. This page copies text locally; it does not run the prompt.
Design an evaluation for [TASK] using [INPUT CASES]. Define an explicit pass/fail rule for each case before running anything. Record model version, prompt version, tool access, attempt count, total cost and time to an accepted result. Include all failed attempts. Separate measured values from unknown values. Return a blank scorecard and a repeatable run protocol. Do not choose a winner without completed trials.
Review checklist
- Freeze the input cases and acceptance rules.
- Record model, prompt and tool versions.
- Count retries and failed attempts in cost and elapsed time.
- Repeat trials and report spread as well as the average.
Keep the resource
Download the complete note ↓Markdown · explanation, example, prompt and checklistDownload the prompt ↓Plain text · ready to adaptOpen the full-size visual ↓SVG · scalable reference diagramDocumentation & scope
OpenAI: evaluation best practices ↗
This is an original workflow template with an illustrative example. It does not report completed model tests or measured performance. Provider APIs can change; check the linked documentation for your exact integration.